Moonshot AI builds frontier open weight language models for reasoning, coding, and agentic workflows
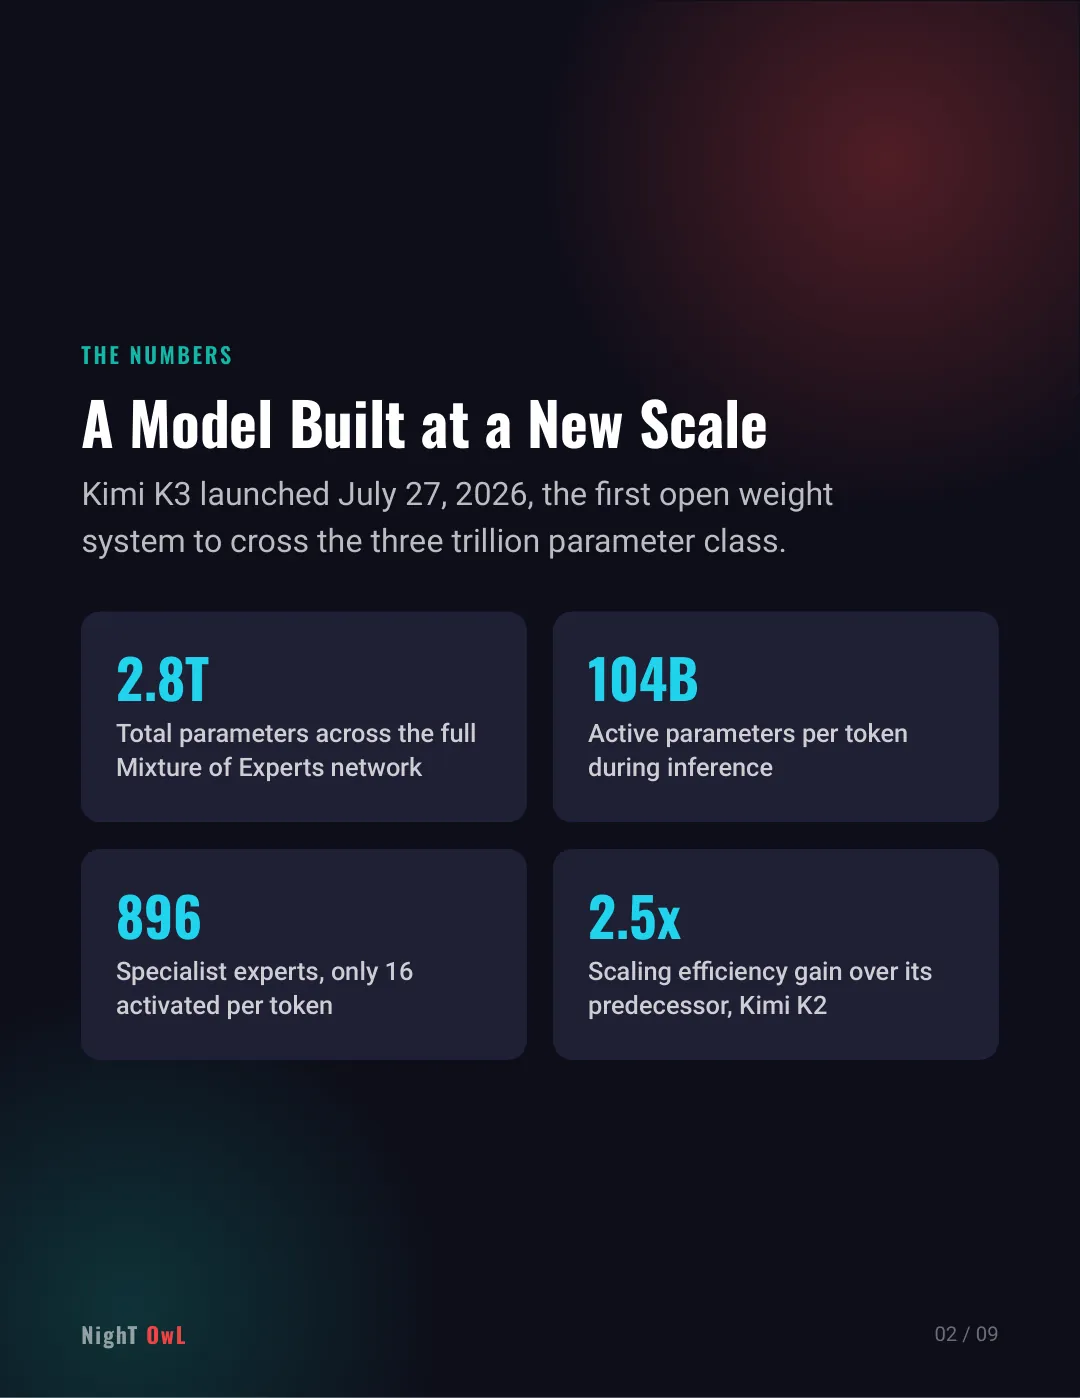
Its latest release, Kimi K3, is a 2.8 trillion parameter Mixture of Experts model, the first open weight system to cross the 3 trillion parameter class, activating just 104 billion parameters per token.
AWS now supports its deployment through SageMaker HyperPod and Amazon EKS, bringing frontier scale inference into production.
Read the slides as text
Slide 1
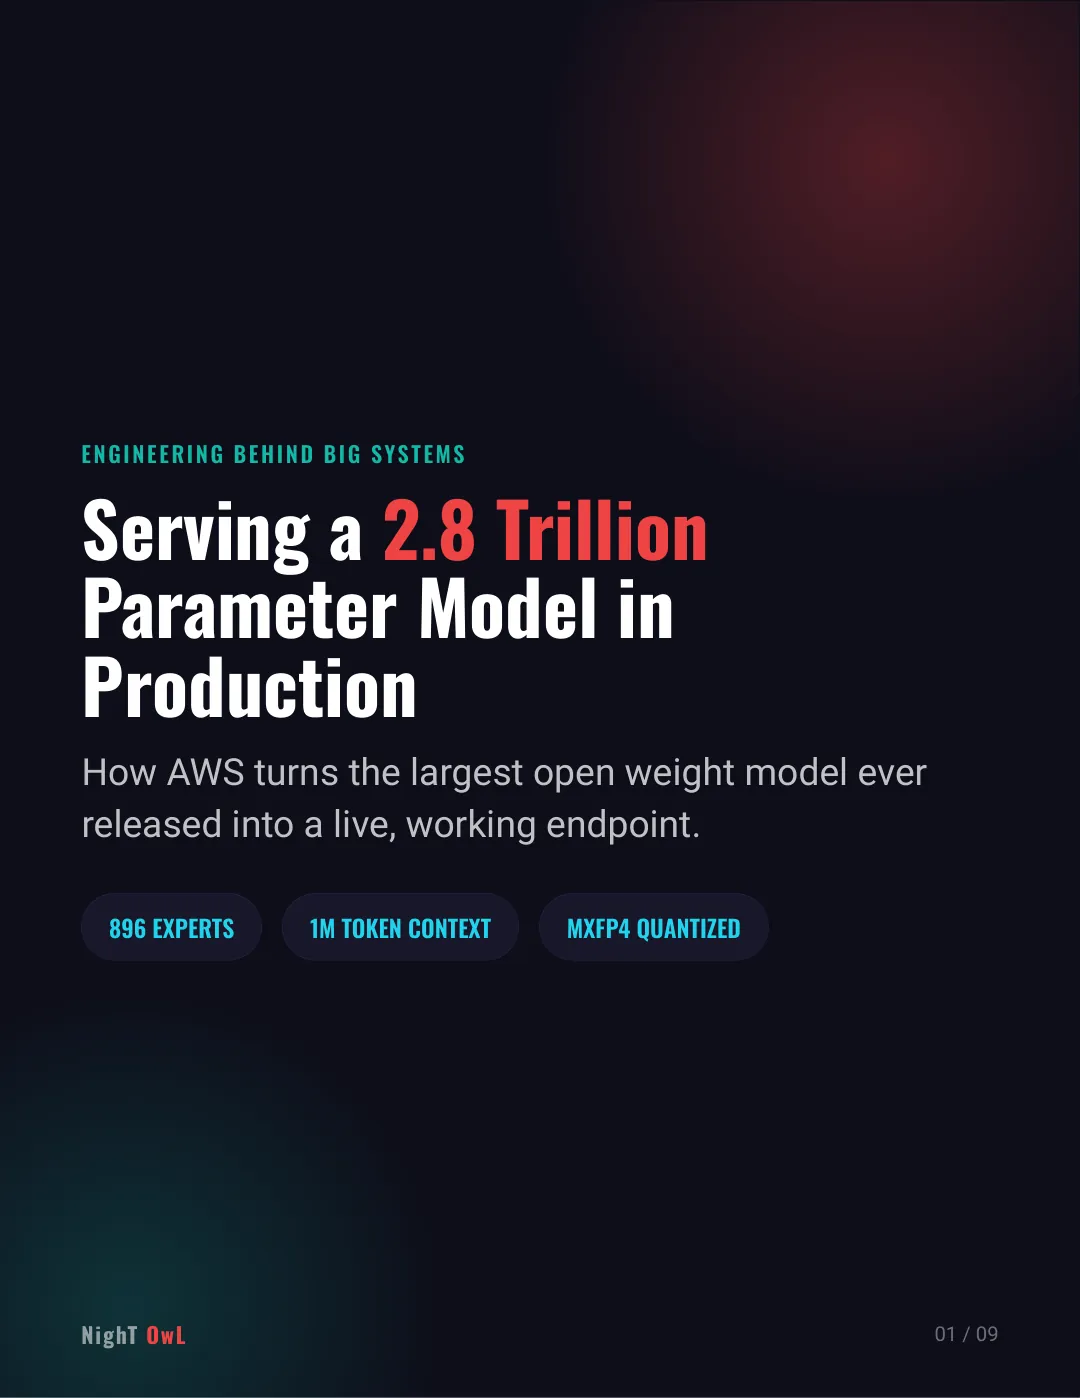
ENGINEERING BEHIND BIG SYSTEMS
Serving a 2.8 Trillion
Parameter Model in
Production
How AWS turns the largest open weight model ever
released into a live, working endpoint.
896 EXPERTS
1M TOKEN CONTEXT
MXFP4 QUANTIZED
NighT OwL
01 / 09
Slide 2
THE NUMBERS
A Model Built at a New Scale
Kimi K3 launched July 27, 2026, the first open weight
system to cross the three trillion parameter class.
2.8T
Total parameters across the full
Mixture of Experts network
104B
Active parameters per token
during inference
896
Specialist experts, only 16
activated per token
2.5x
Scaling efficiency gain over its
predecessor, Kimi K2
NighT OwL
02 / 09
Slide 3
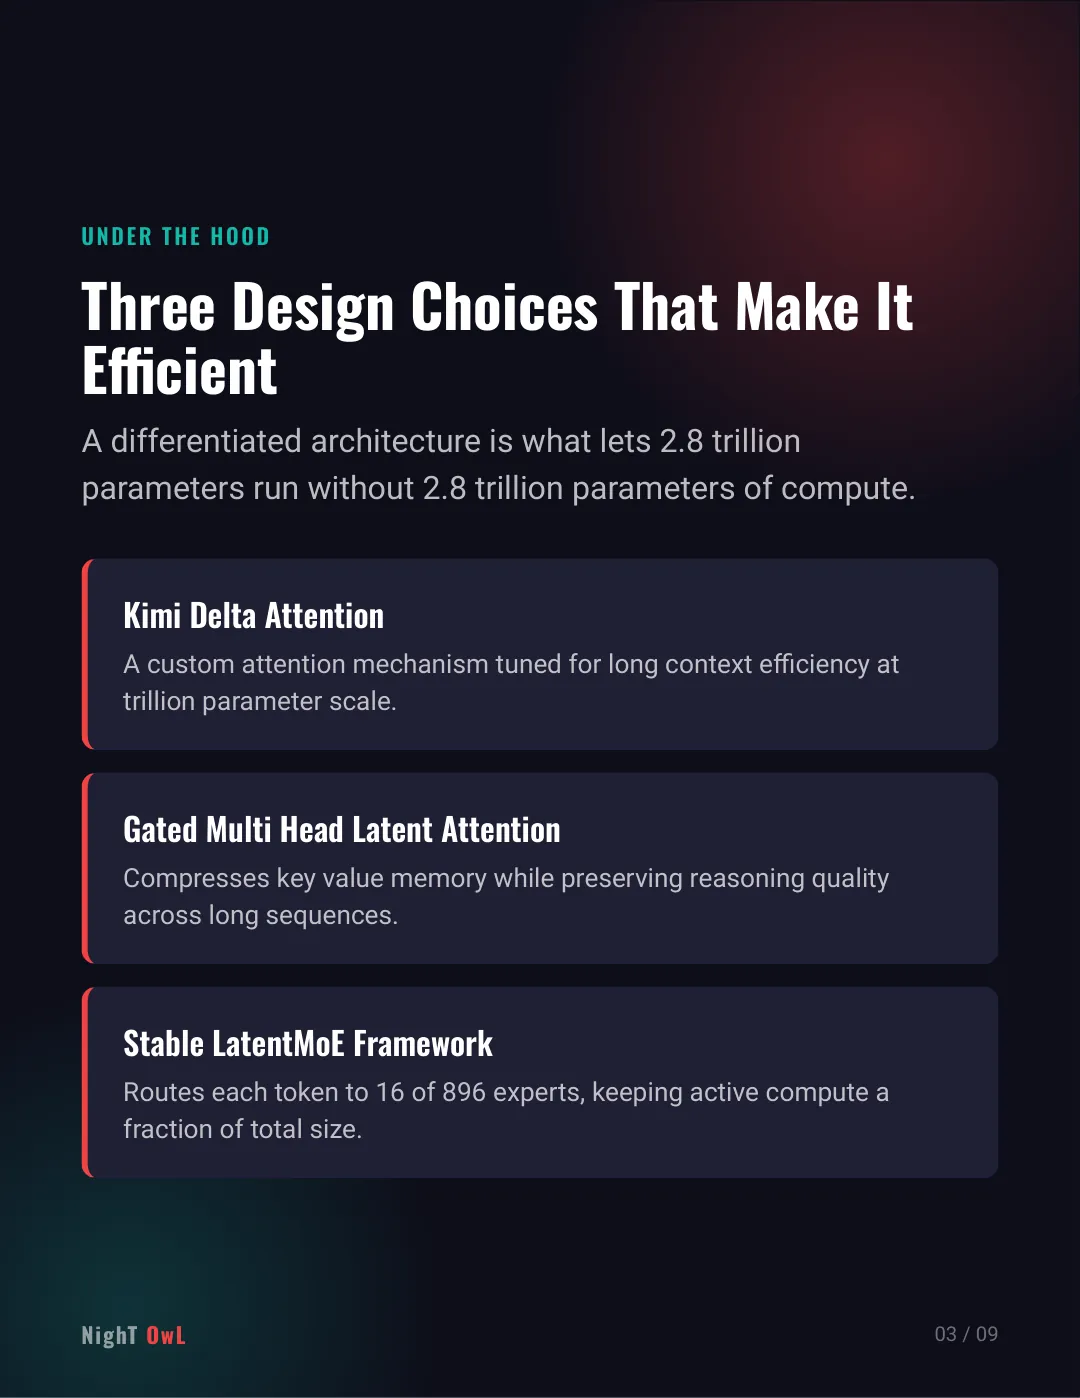
UNDER THE HOOD
Three Design Choices That Make It
Efficient
A differentiated architecture is what lets 2.8 trillion
parameters run without 2.8 trillion parameters of compute.
Kimi Delta Attention
A custom attention mechanism tuned for long context efficiency at
trillion parameter scale.
Gated Multi Head Latent Attention
Compresses key value memory while preserving reasoning quality
across long sequences.
Stable LatentMoE Framework
Routes each token to 16 of 896 experts, keeping active compute a
fraction of total size.
NighT OwL
03 / 09
Slide 4
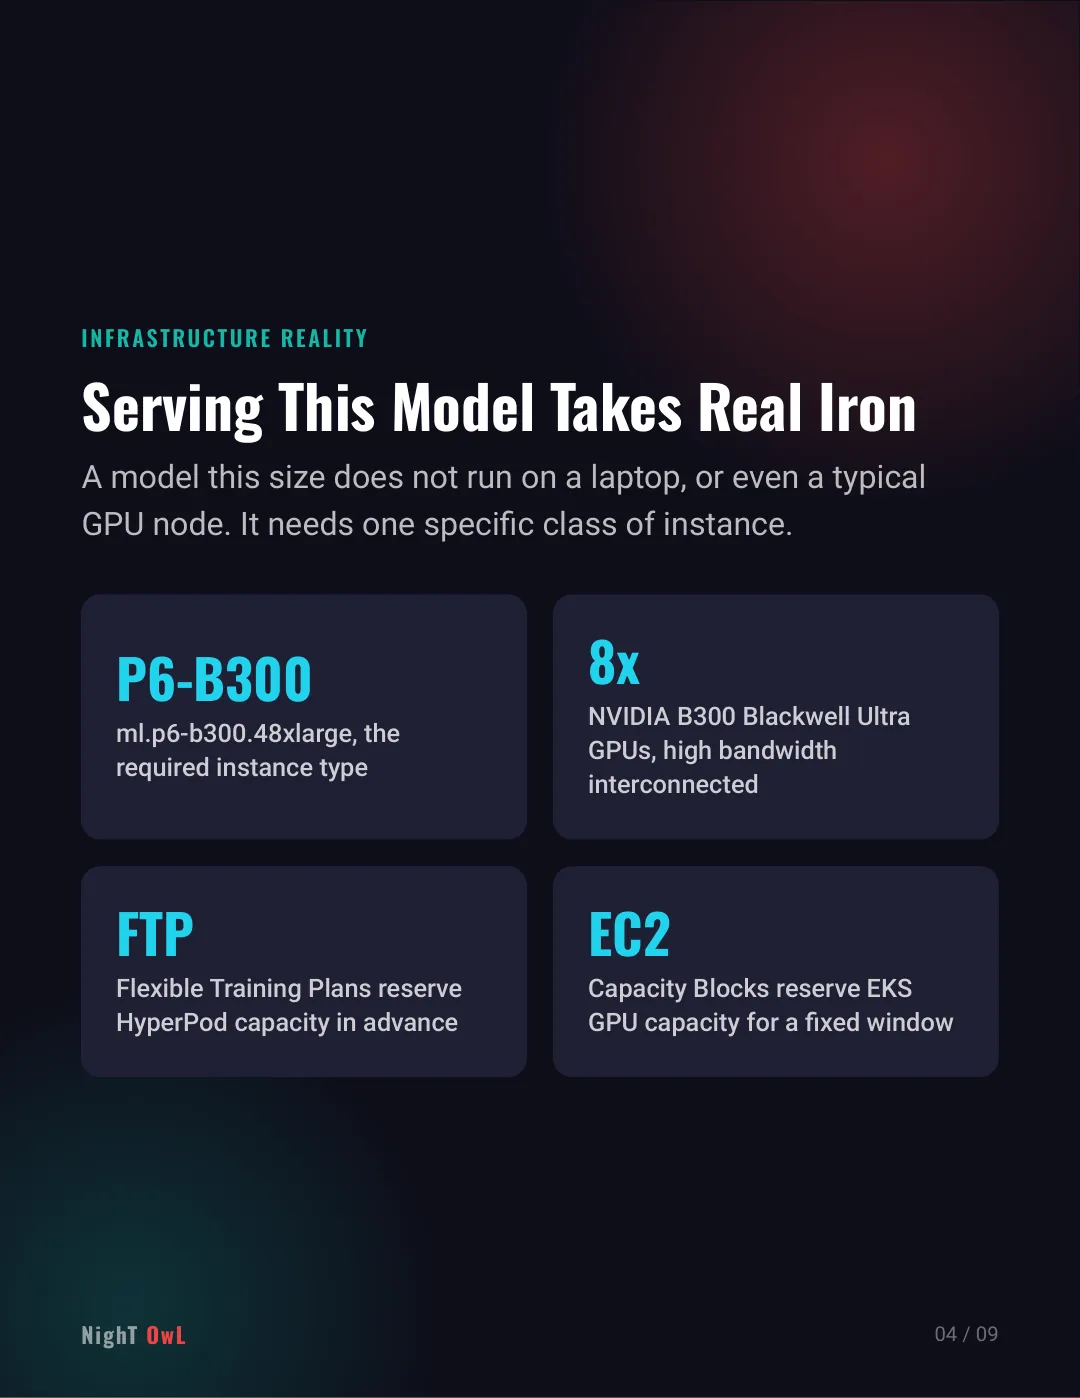
INFRASTRUCTURE REALITY
Serving This Model Takes Real Iron
A model this size does not run on a laptop, or even a typical
GPU node. It needs one specific class of instance.
P6-B300
ml.p6-b300.48xlarge, the
required instance type
8x
NVIDIA B300 Blackwell Ultra
GPUs, high bandwidth
interconnected
FTP
Flexible Training Plans reserve
HyperPod capacity in advance
EC2
Capacity Blocks reserve EKS
GPU capacity for a fixed window
NighT OwL
04 / 09
Slide 5
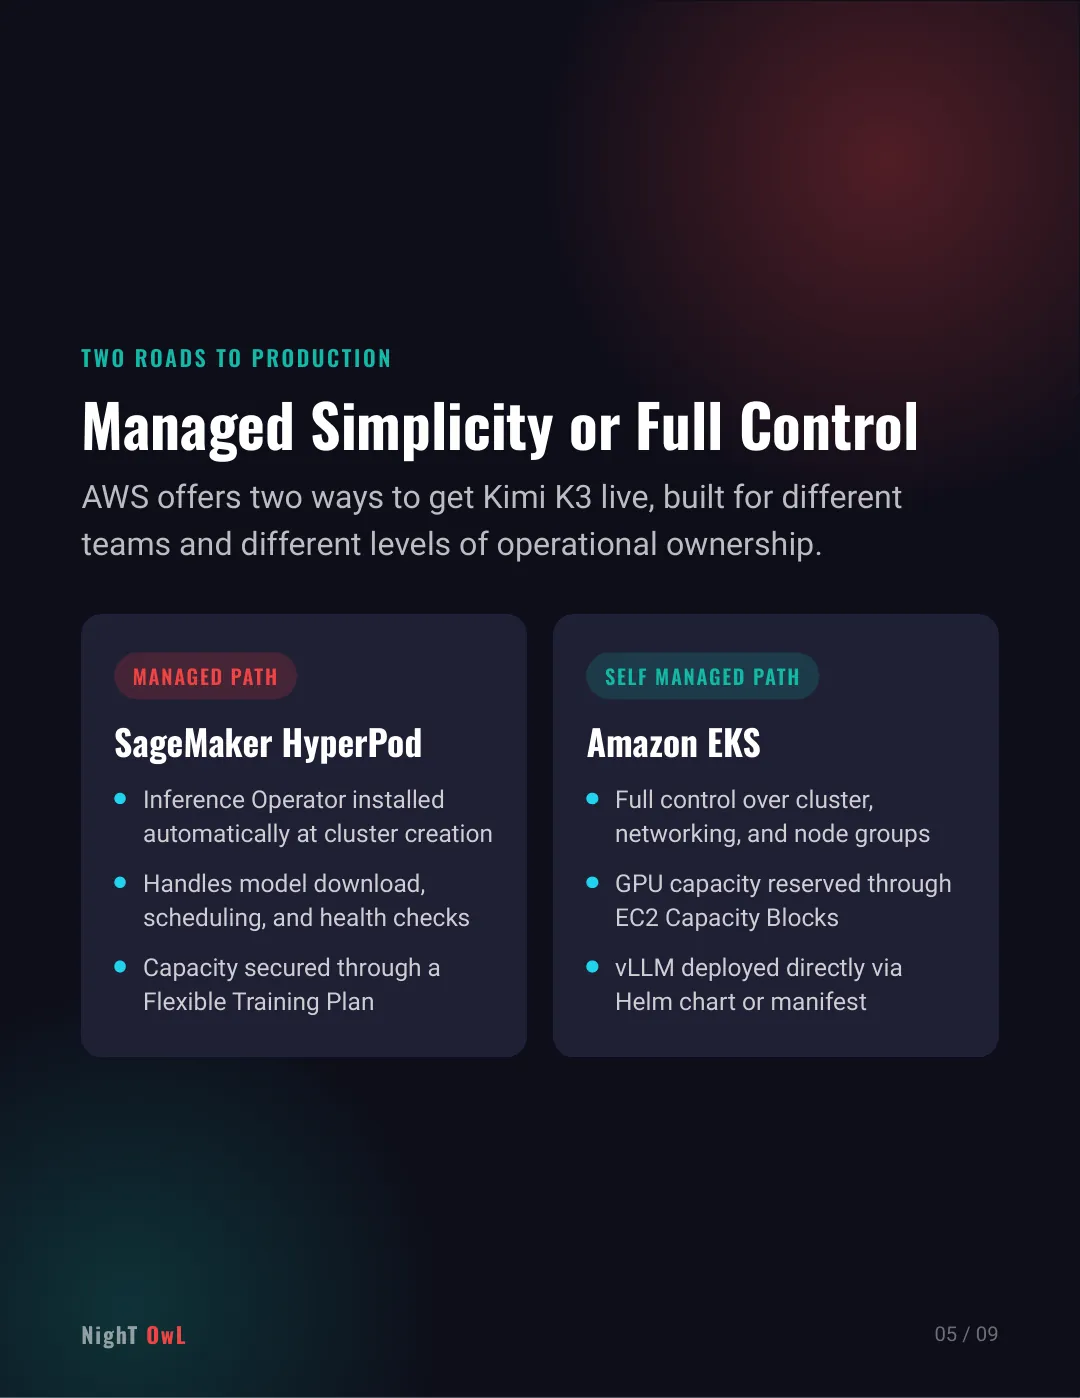
TWO ROADS TO PRODUCTION
Managed Simplicity or Full Control
AWS offers two ways to get Kimi K3 live, built for different
teams and different levels of operational ownership.
MANAGED PATH
SageMaker HyperPod
SELF MANAGED PATH
Amazon EKS
Inference Operator installed
automatically at cluster creation
Handles model download,
scheduling, and health checks
Capacity secured through a
Flexible Training Plan
Full control over cluster,
networking, and node groups
GPU capacity reserved through
EC2 Capacity Blocks
vLLM deployed directly via
Helm chart or manifest
NighT OwL
05 / 09
Slide 6
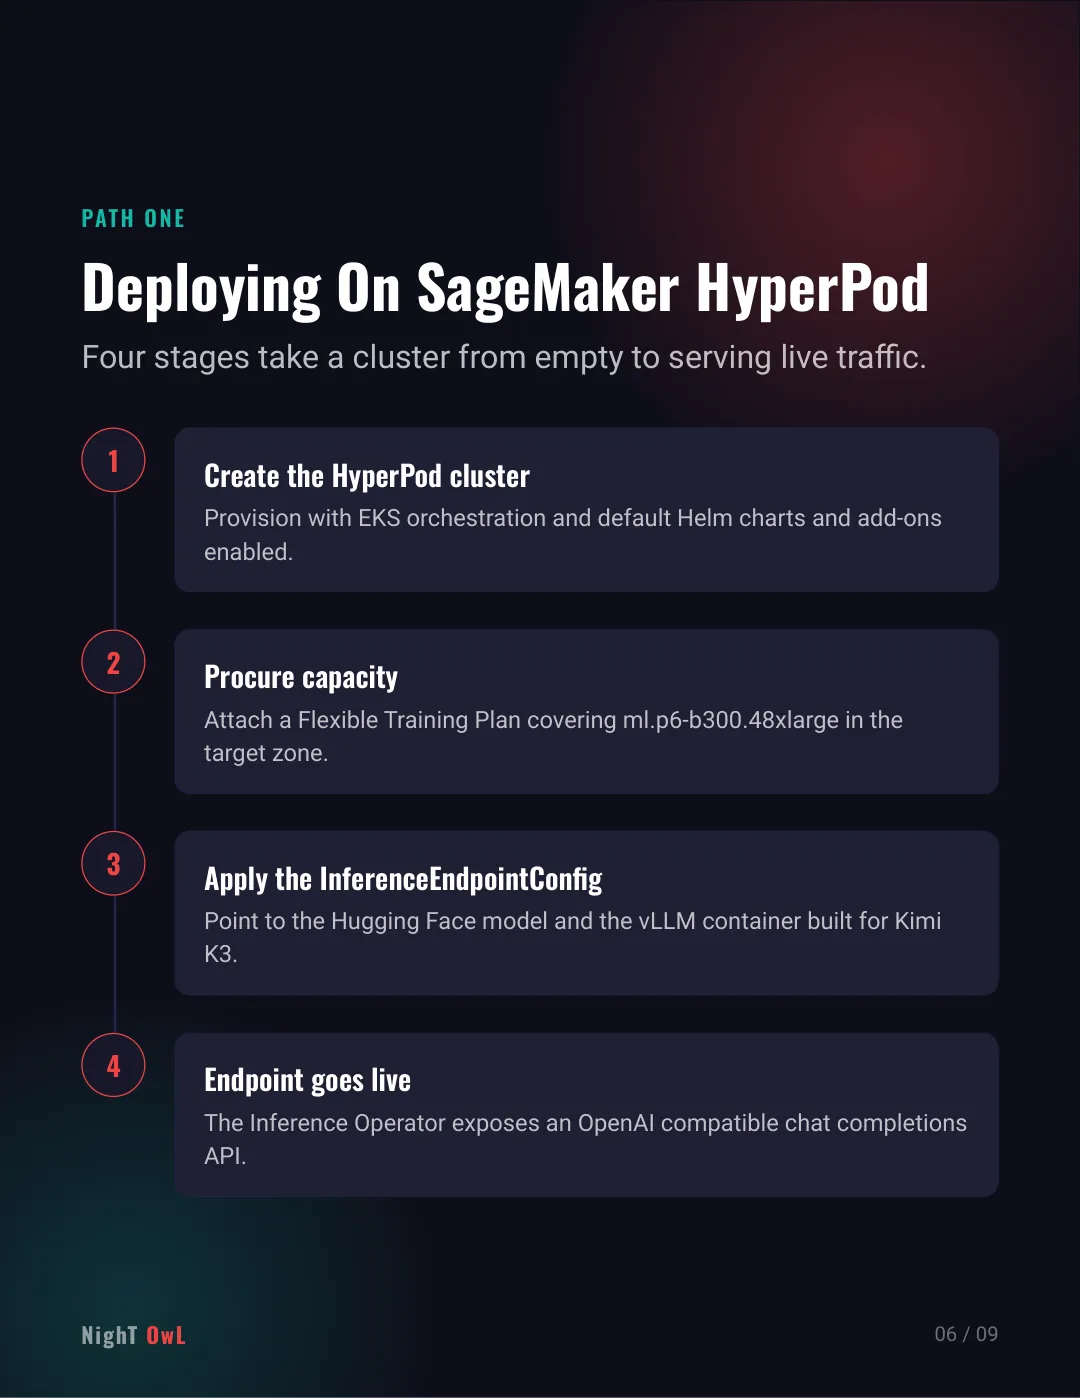
PATH ONE
Deploying On SageMaker HyperPod
Four stages take a cluster from empty to serving live traffic.
Create the HyperPod cluster
Provision with EKS orchestration and default Helm charts and add-ons
enabled.
Procure capacity
Attach a Flexible Training Plan covering ml.p6-b300.48xlarge in the
target zone.
Apply the InferenceEndpointConfig
Point to the Hugging Face model and the vLLM container built for Kimi
K3.
Endpoint goes live
The Inference Operator exposes an OpenAI compatible chat completions
API.
1
2
3
4
NighT OwL
06 / 09
Slide 7
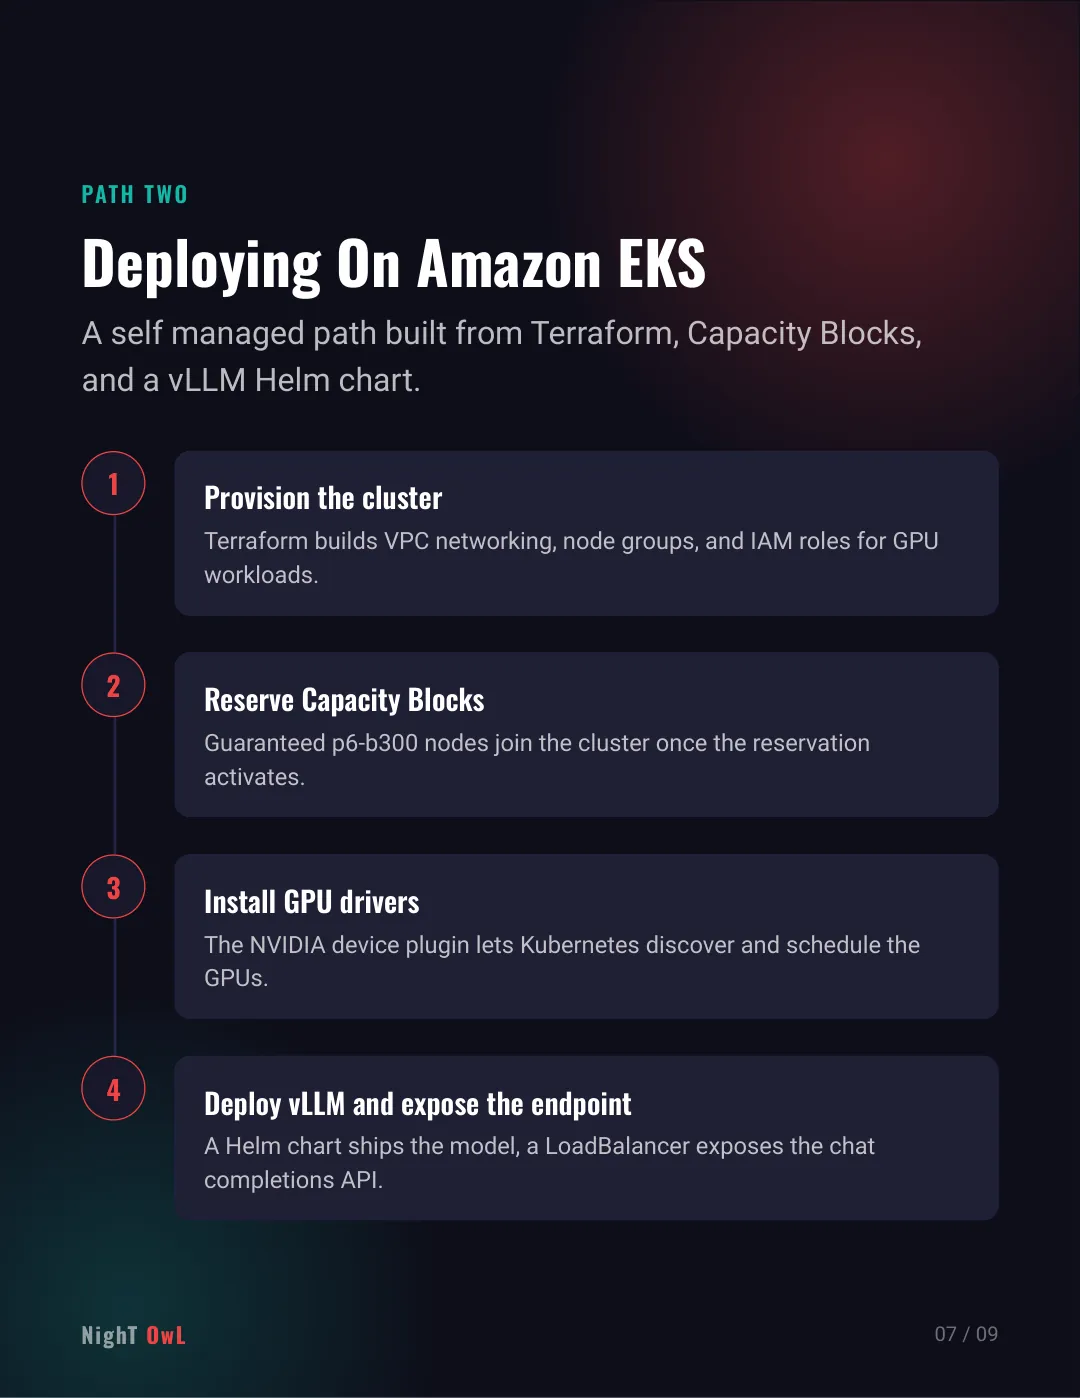
PATH TWO
Deploying On Amazon EKS
A self managed path built from Terraform, Capacity Blocks,
and a vLLM Helm chart.
Provision the cluster
Terraform builds VPC networking, node groups, and IAM roles for GPU
workloads.
Reserve Capacity Blocks
Guaranteed p6-b300 nodes join the cluster once the reservation
activates.
Install GPU drivers
The NVIDIA device plugin lets Kubernetes discover and schedule the
GPUs.
Deploy vLLM and expose the endpoint
A Helm chart ships the model, a LoadBalancer exposes the chat
completions API.
1
2
3
4
NighT OwL
07 / 09
Slide 8
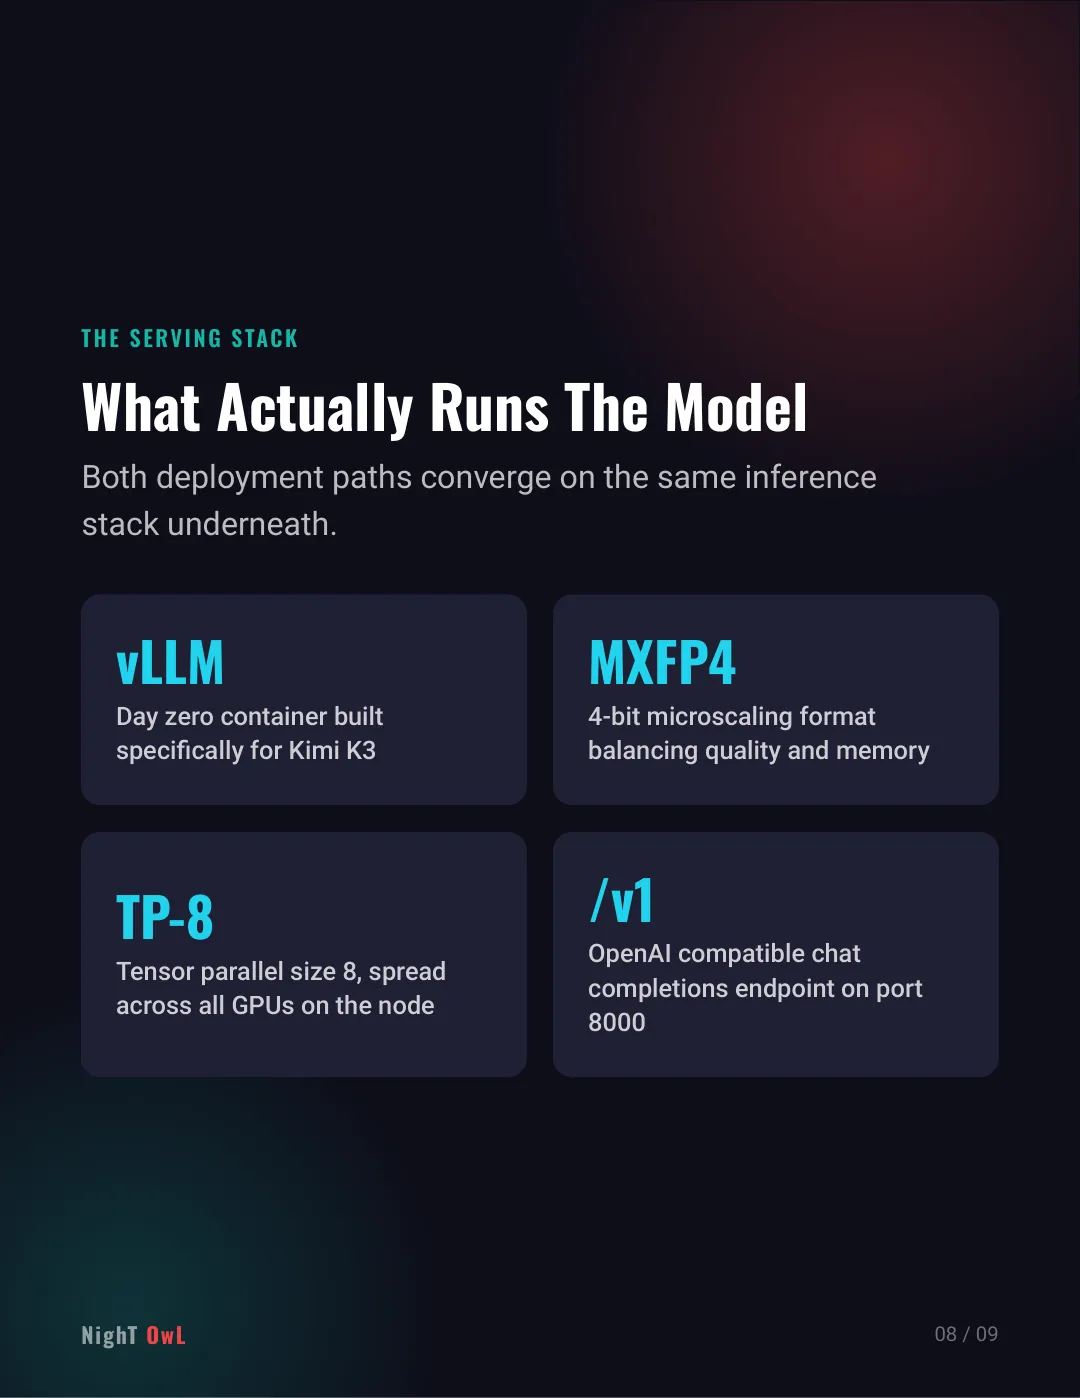
THE SERVING STACK
What Actually Runs The Model
Both deployment paths converge on the same inference
stack underneath.
vLLM
Day zero container built
specifically for Kimi K3
MXFP4
4-bit microscaling format
balancing quality and memory
TP-8
Tensor parallel size 8, spread
across all GPUs on the node
/v1
OpenAI compatible chat
completions endpoint on port
8000
NighT OwL
08 / 09
Slide 9
THE TAKEAWAY
Model Size Was Never The Bottleneck
The real engineering work starts after the weights are
downloaded.
01
Frontier scale models now ship as open weights, ready to self host on
day one.
02
Capacity planning, not model access, becomes the real constraint at
this scale.
03
Health checks, auto recovery, and endpoint readiness define
production grade serving.
NighT OwL
09 / 09